Solutions · Ground autonomy
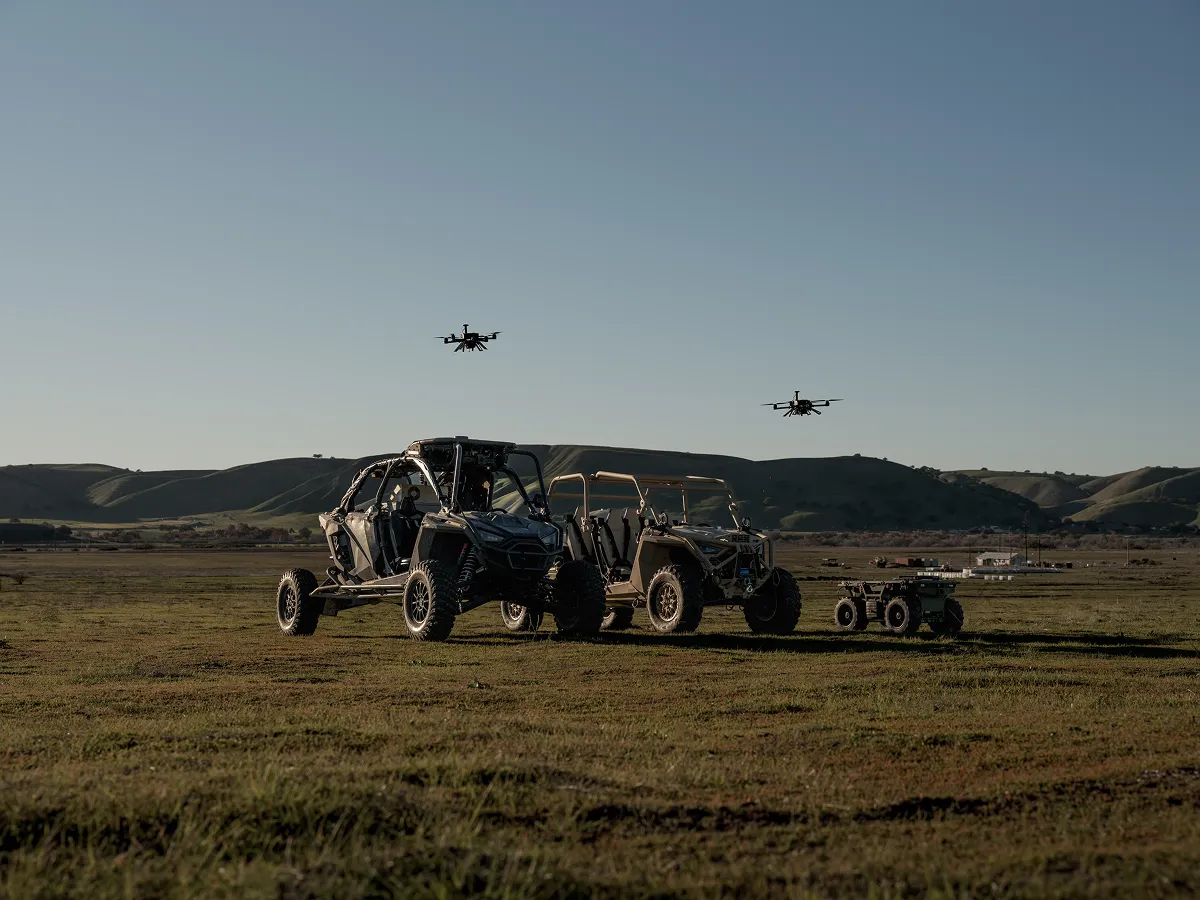
Repeatable field trials for UGVs and robotics
Synchronized runs, automatic mission checks, and fleet-wide comparisons, from one prototype to dozens of vehicles.

The challenge
Ground autonomy programs generate terabytes of data per trial.
Varied terrain and unpredictable conditions make every run different. Instead of juggling domain-specific tools, ground teams work in Nominal, so test cycles move faster, debugging gets simpler, and scaling to dozens of vehicles becomes practical.
Where teams get stuck
Slow annotation
Manual tagging creates bottlenecks and delays retraining cycles.
Missed context
Logs can't capture operator intent or live situational awareness.
Heavy post-test workload
Teams spend hours retro-tagging and aligning events after missions.
Disconnected workflows
Engineers, annotators, and operators lack a shared system of record.
Features
Faster answers, safer systems
Whether you're reviewing one run or monitoring a fleet, Nominal puts vehicles, missions, and operators on one timeline.
Synchronize runs instantly
Video, logs, and telemetry from every mission land in one catalog, with synchronized playback instead of juggling tools.
Track vehicle reliability
Every UGV has a profile of hardware, firmware, and payloads, tied to mission outcomes over time.
Validate automatically
Did the system detect the obstacle? Did it brake in time? Mission checks answer on every run.
Review as a team
Findings, annotations, and decisions stay in one place, with no scattered threads.
Report with confidence
Deliver regulator-ready and customer-facing reports with traceable evidence.
Scale beyond single missions
Compare vehicles in the same environment and correlate failures across days, terrain, and configurations.
From the field
Teams building critical hardware trust Nominal
“We're at an inflection point where our testing infrastructure needs to match the pace and rigor of production. Nominal gives us a single source of truth across every test environment, simulation, HIL, and vehicle so our teams can validate faster and ship with confidence.”
 Scott PhilipsChief Innovation Officer
Frequently asked questions
Can operators annotate events during a run?
Yes. Operators can annotate in the field, including live audio-transcribed notes, and those annotations sit on the same timeline as video, logs, and telemetry.
Can mission checks run automatically?
Yes. Define checks once, such as whether the vehicle detected an obstacle or braked in time, and Nominal runs them on every mission.
Can we compare vehicles across a fleet?
Yes. Compare performance across vehicles in the same environment and correlate failures across days, terrain, and configurations.
Can Nominal help curate training data?
Yes. Search annotated runs across robots, missions, and tasks to build and track training sets.